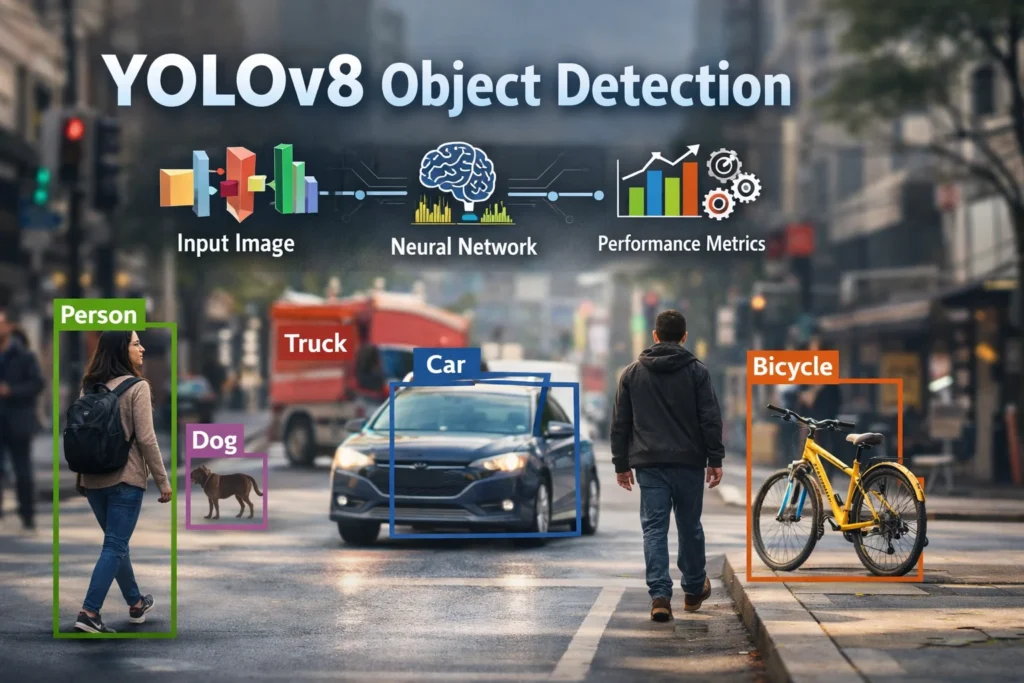
Computer vision keeps evolving fast. Object detection models are becoming more accurate, faster, and easier to use. One of the biggest steps forward in this space is yolov8, the latest model in the YOLO family. It brings architectural improvements, better training behavior, and a cleaner developer experience.
In this guide, you will learn what YOLOv8 is, how it works, how it compares to earlier versions, and when you should use it. Everything is explained in simple language, with practical insights.
What Is YOLOv8?
YOLOv8 is a modern object detection model developed by Ultralytics. It supports multiple computer vision tasks using a single framework.
You can use it for:
- Object detection
- Image classification
- Instance segmentation
The model focuses on speed, accuracy, and usability. It removes several limitations found in older YOLO versions and simplifies training and deployment.
Evolution of YOLO Models
The YOLO family started in 2015. The goal was simple: detect objects in real time using one neural network.
Over time, each version improved performance and efficiency.
- YOLOv1–v3: Introduced real-time detection
- YOLOv4: Focused on speed and accuracy balance
- YOLOv5: Popularized PyTorch and easy training
- YOLOv7: Improved efficiency with advanced training tricks
YOLOv8 builds on this history. It removes anchors, refines the backbone, and improves training stability.
YOLOv8 Architecture Explained
The architecture of YOLOv8 is cleaner and more flexible than previous versions. It improves both accuracy and speed.
Anchor-Free Detection
Older YOLO models relied on anchor boxes. These required manual tuning and often failed on custom datasets.
YOLOv8 removes anchors completely.
Instead, the model predicts object centers directly. This:
- Reduces complexity
- Improves generalization
- Speeds up Non-Maximum Suppression
Anchor-free detection is one of the biggest upgrades in this version.
C2f Module in the Backbone
YOLOv8 replaces the C3 module with a new C2f module.
The key idea is simple. Instead of using only the last bottleneck output, the model concatenates features from multiple bottlenecks.
This improves:
- Gradient flow
- Feature reuse
- Training stability
The result is better accuracy without heavy computation.
Decoupled Head Design
In earlier YOLO versions, classification and box regression shared the same head.
YOLOv8 separates them.
This decoupled head allows:
- Better localization
- More accurate classification
- Faster convergence during training
It also works well with anchor-free detection.
Improved Loss Functions
YOLOv8 uses smarter loss calculations.
It combines:
- Binary Cross-Entropy for classification
- Complete IoU for bounding boxes
- Distribution Focal Loss for better boundary prediction
These losses help the model focus on hard examples and reduce false positives.
YOLOv8 Model Variants (n, s, m, l, x)
YOLOv8 comes in five sizes. Each size targets a different use case.
| Model | Best For |
| YOLOv8n | Edge devices, low power |
| YOLOv8s | Fast inference, small datasets |
| YOLOv8m | Balanced performance |
| YOLOv8l | High accuracy needs |
| YOLOv8x | Maximum accuracy |
Which Version Should You Choose?
Choose based on:
- Hardware availability
- Dataset size
- Real-time requirements
If speed matters most, use smaller models. If accuracy is critical, go with larger ones.
YOLOv8 Training Pipeline
Training YOLOv8 is simpler than older versions.
Dataset Format
The model uses the same TXT annotation format as YOLOv5. Each image has a label file with class IDs and normalized bounding boxes.
This makes migration easy.
Data Augmentation and Mosaic
YOLOv8 applies data augmentation during training.
Mosaic augmentation combines four images into one. This improves robustness.
However, YOLOv8 automatically disables mosaic in the final training epochs. This helps the model fine-tune on natural images and improves final accuracy.
YOLOv8 Performance and Benchmarks
COCO Benchmark Results
On the COCO dataset, YOLOv8 achieves state-of-the-art results at comparable inference speeds.
Medium and large models show strong mAP scores while maintaining real-time performance.
RF100 Benchmark Performance
YOLOv8 also performs well on domain-specific datasets.
On the RF100 benchmark:
- It shows fewer performance drops
- It generalizes better to unseen domains
- It outperforms YOLOv5 and YOLOv7 in most categories
This makes it suitable for real-world applications.
YOLOv8 vs YOLOv5 vs YOLOv7
Here is a quick comparison:
| Feature | YOLOv5 | YOLOv7 | YOLOv8 |
| Anchor-free | ❌ | ❌ | ✅ |
| Decoupled head | ❌ | ❌ | ✅ |
| Training stability | Good | Better | Best |
| Ease of use | High | Medium | Very high |
YOLOv8 offers the best balance of usability and performance.
YOLOv8 Hardware Requirements
YOLOv8 runs on a wide range of devices.
CPU Inference
Small models can run on CPUs. Performance is slower but usable for low-volume tasks.
GPU and Edge Devices
With GPUs, YOLOv8 runs in real time.
It also works well on:
- NVIDIA Jetson devices
- ARM-based systems
- Embedded AI hardware
This flexibility makes it ideal for edge deployment.
YOLOv8 Installation and Usage
Using the CLI
The CLI allows quick training and inference.
You can train, validate, predict, and export models using simple commands.
This reduces setup time and errors.
Using the Python API
The Python API gives full control.
You can:
- Load pretrained weights
- Train custom datasets
- Export models to ONNX or TensorRT
This makes integration into existing pipelines easy.
YOLOv8 Deployment Options
YOLOv8 supports multiple deployment paths.
Cloud Deployment
You can deploy models using hosted APIs for scalable inference.
This is useful for web apps and large workloads.
Edge and On-Device Deployment
For privacy and low latency, deploy on device.
YOLOv8 works well with Docker, inference servers, and lightweight runtimes.
YOLOv8 Applications
YOLOv8 fits many industries.
Retail and Analytics
- People counting
- Shelf monitoring
- Queue detection
Autonomous Systems
- Obstacle detection
- Traffic monitoring
- Navigation support
Security and Surveillance
- Intrusion detection
- Object tracking
- Smart city systems
YOLOv8 Limitations and Challenges
No model is perfect.
YOLOv8 still has limits:
- Large models require powerful GPUs
- Performance depends heavily on data quality
- Fine-tuning is needed for niche domains
Understanding these helps avoid unrealistic expectations.
Common YOLOv8 Errors and How to Fix Them
Annotation Issues
- Incorrect bounding boxes
- Wrong class IDs
Fix by validating labels before training.
Overfitting or Underfitting
- Use more data
- Adjust epochs and augmentation
- Choose the right model size
Small tweaks often bring big improvements.
Conclusion: Is YOLOv8 Right for You?
YOLOv8 is one of the most practical object detection models available today. It combines modern architecture, strong benchmarks, and excellent usability.
If you want fast training, clean deployment, and reliable results, yolov8 is a strong choice for both research and production.